 mrsaynothing.dev

why is google not indexing my site — the 199-page walk-back
Google quietly stopped indexing this site — dead slugs behind 301s. The audit, the 199-row alias map, the 410 graveyard, and the numbers ten days on.
Google quietly stopped indexing this site — dead slugs behind 301s. The audit, the 199-row alias map, the 410 graveyard, and the numbers ten days on.
systemctl says your unit is masked and won't start. The mask is one symlink to /dev/null — three commands cure it, and systemd-delta lists every mask.
The chat ends and ollama still holds the model — 2.97 GiB for five measured minutes. Stop doors: ollama stop, keep_alive 0, --keepalive, OLLAMA_KEEP_ALIVE.
Robots.txt is a sign, not a lock — our 28-day census caught GPTBot on 155 pages without reading it once. The five doors that actually stop AI crawlers, ranked.
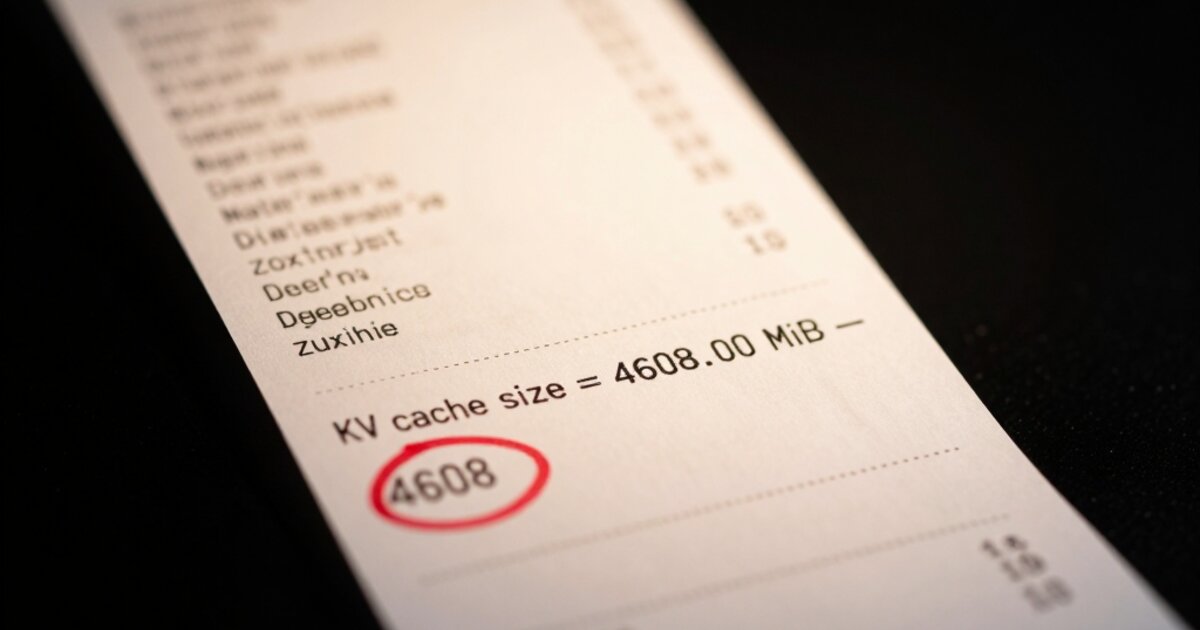
q8_0 keeps the KV cache at 17/32 of f16 and q4_0 at 9/32 — at 32k context the bill is 4608 MiB against a 2382 MiB model. Receipts, crossover, speed tax.
systemd service restart on failure has a fuse: five crashes in ten seconds trip the start limit and park the unit. Bench: the trip, the dead slot, the cures.
Eight weeks of bot logs: robots.txt drew 343 fetches, our API 111, llms.txt 17. What is llms.txt for? The answer engines never came — receipts inside.
Restart a systemd service daily with a timer, not a cron line: OnCalendar=daily, RandomizedDelaySec, Persistent. Bench-fired on systemd 262 — receipts inside.
Show the reason a systemd service restarted: status shrugs, the journal confesses. Five death codes from a live bench — and the one death it calls success.
Ollama ships an audio model that hears, but the API has no working ear. We fed real speech through the image door — receipts, garbles, full token bill.
Ollama's web search API shipped September 2025. We knocked keyless tonight: 401 in 0.13 and 0.15 seconds. The key, the limits, and the part that isn't local.
Seven nights, 8,654 bot knocks, 247 human visits. AI crawlers vs search crawlers, measured: Perplexity beat OpenAI 9-to-1 and 65% knocked unnamed.
A thinking model spent 866 tokens and 53 seconds to say “Bug”. The three switches that turn thinking off in Ollama — and the measured bill that says when to flip them.
Best local LLM for coding on 8GB VRAM? Check the fit table first — an 8GB card holds 8.59 decimal GB but only ~7.3 usable GiB. Sizes measured today, KV math shown, one honest fit table — the 9B the tables love fails at 8k.
Weights + KV cache + overhead: the three numbers that decide whether a GGUF quant fits — printed as formulas, checked against four public GGUF files today.
ollama v0.40.13 brings Liquid AI's LFM3 — text, audio, omni — to Linux and Windows. The 1.7B rung benched on a CPU VM: 17 tok/s, 1.2 GB, one honest catch.
Ollama wrapped LFM3 for pull-and-run the same day; llama.cpp v0.8.0 is where that week actually landed — realtime audio endpoints, six new architectures, sparse attention on a fused mask, MoE experts cached on host RAM.
Two decision models shipped into ollama five days apart: d3 (2b-27b, runs on Linux CPU today) and d1 (2b, Apple-only this week). Which one to call.
Does vLLM support GGUF? Yes — on GPUs only. The honest vLLM–GGUF matrix: six green hardware rows, every CPU row red, and the border rule the guides skip.
Nine times in ten it's CPU offload you didn't notice — ollama ps shows the split in one line. Then: cold reloads after the five-minute keep-alive, an oversized context, a heavier quant than you need, and swap.
Ollama never refuses a model that misses VRAM — it splits it. Fitted layers stay on the GPU, the rest fall back to CPU, and tok/s falls with them. How to see the split in one line, and the three honest fixes, ranked.
Ollama's d3 scores tickets instead of talking. The 2b and 4b rungs on an 8-core CPU box: yes 98% in 0.8 s warm, a 64 KiB door fuse, and a verdict that wobbles.
Ollama v0.40.9 ships d3: four decision models from vLLM Semantic Router that return scored choices instead of chat. Sizes, memory, index scores, fine print.
Perplexity's 27B decision model sits in Ollama's library. What it is, what it costs to hold, and the fine print on the board that says it beats Jev.
The e2e suite expected 401 and got 429 — the daily IP cap had spent the day's budget on earlier runs. The wall, built as a machine: twelve window slots, a tape that remembers, an arm that drops at three.